Sovereign Stack
What Vector Search Misses, and What To Put Next To It
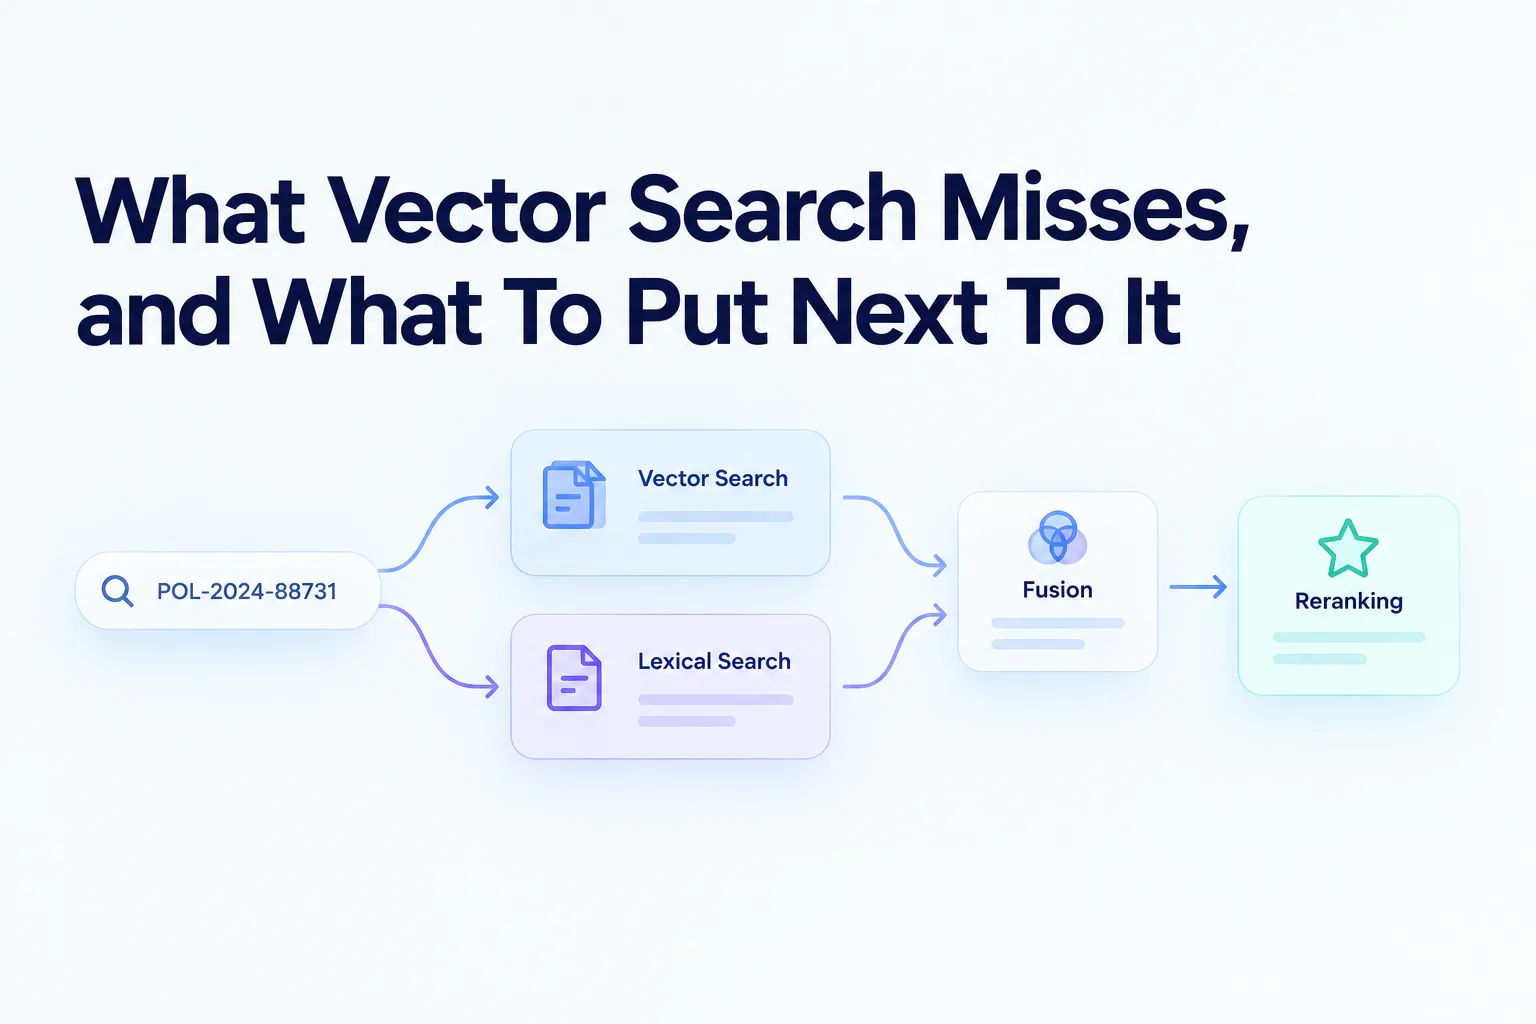
Someone types a policy number into the internal assistant and gets back three documents about something else entirely. The policy exists. Its number appears, verbatim, in a document the system has indexed. Search still missed it.
This surprises people because vector search is the part of the stack with the best reputation. It handles synonyms, it understands paraphrase, it finds the right passage when the user's wording is nothing like the document's. All of that is true, and none of it helps with an identifier.
Vector search finds things that mean the same. Some queries need things that are the same.
Why the Identifier Fails
An embedding model turns text into a vector that encodes meaning. Training teaches it that "terminate the agreement" and "end the contract" belong near each other. Nothing teaches it that POL-2024-88731 is meaningfully different from POL-2024-88713, because to a model trained on language, those two strings are nearly identical and almost equally meaningless.
The same weakness shows up in a family of queries that enterprise users produce constantly: part numbers, invoice references, employee IDs, error codes, legal citations, rare proper nouns, and abbreviations specific to the company. Anything whose value lies in exactness rather than meaning.
There is a second failure that is easier to miss. Dense retrieval tends to be weak on negation. "Suppliers not covered by the framework agreement" and "suppliers covered by the framework agreement" occupy almost the same position in vector space, and the retrieved passages are frequently the wrong half of the distinction.
The Technique That Never Went Away
Lexical search, in the BM25 family, ranks passages by the terms they actually contain, weighted so that rare terms count more and long documents do not win by sheer length.
That weighting is exactly what identifier queries need. POL-2024-88731 appears in almost no documents, which makes it an extremely strong signal, and a lexical index finds the one passage containing it immediately.
It is also the half that fails at everything vector search is good at. A user asking "what happens if we end the contract early" will not match a document that only ever says "termination for convenience".
The two methods fail in different directions, which is why the sensible architecture runs both.
Merging Two Ranked Lists
Running both retrievers produces two ranked lists that have to become one. The score values are not comparable, since one is a similarity measure and the other a term-weighting sum, so merging on raw scores requires normalization that tends to be fragile.
The common approach is to merge on rank instead of score. Reciprocal rank fusion gives each passage a contribution of one divided by a constant plus its rank in each list, then sums those contributions across lists. A passage ranked highly by both retrievers rises; a passage found only by the lexical side still surfaces if it ranks near the top there.
The constant, commonly set around 60, controls how much a top rank is worth relative to a merely good one. It is worth tuning against your own evaluation set rather than inheriting it, because the right value depends on how deep your candidate lists go.
The Third Stage: Reranking
Fusion produces a decent candidate set. Precision usually comes from a reranker, a model that takes the query and one passage together and scores how well that passage answers that query.
This is more expensive per comparison than retrieval, because nothing can be precomputed: the score depends on the pair. That is also why it is more accurate. Retrieval embeddings are computed before anyone asks anything, so they cannot be query-specific. A reranker reads both sides.
The usual shape is wide then narrow: retrieve perhaps fifty candidates from each method, fuse, rerank the merged set, and send the top handful to the model.
| Stage | What it is good at | What it misses |
|---|---|---|
| Lexical (BM25) | Identifiers, rare terms, exact names, acronyms your company invented | Synonyms, paraphrase, anything worded differently from the document |
| Vector | Meaning, paraphrase, cross-lingual matching, vague questions | Exact strings, near-identical identifiers, negation |
| Fusion | Combining both without comparing incompatible scores | Nothing it was not given by the two retrievers |
| Reranker | Precision within the candidate set, query-specific judgment | Anything that never made the candidate set |
The last row is the one worth sitting with. A reranker cannot recover a passage that neither retriever returned. Recall is decided earlier, which is why the candidate set is the part to widen when quality is poor and the part to narrow when latency is poor.
What It Costs
Two indexes mean two write paths, two sets of ingestion bugs, and more storage. Lexical indexes are cheap compared to vectors, but they are another thing to keep in sync, and a document present in one and missing from the other produces results that are hard to explain.
Reranking adds a model call on the critical path, scaling with candidate set size. Fifty candidates reranked is a different latency budget from ten, and that choice is the main dial between accuracy and speed.
Query routing is tempting and risky. Sending identifier-shaped queries only to the lexical side saves work, but a classifier that misroutes sends a query to the wrong retriever entirely, and that failure is invisible in the answer. Running both and fusing is harder to get spectacularly wrong.
How To Check Yours
Take ten real questions containing identifiers, codes or internal abbreviations, and ten phrased in language that appears nowhere in the source documents. Run both sets.
If the first ten fail, there is no lexical path. If the second ten fail, retrieval is lexical-only or the embedding model is a poor fit for your material. If both sets return the right passage somewhere in the candidate list but the answers are still weak, the problem is downstream, in reranking or in how many passages reach the model.
Anvax runs lexical and vector retrieval together with rank-based fusion and a reranking stage, with the entitlement check applied to the candidates that actually reach the model, so precision work and permission enforcement happen in the same place.
If an internal assistant cannot find a document by its reference number, that is not a tuning problem. It is a missing retriever.
Team Anvax writes about enterprise AI governance, audit, and self-hosted deployment for regulated industries. — About Anvax